Inference cost at scale with napkin math

injuly.in

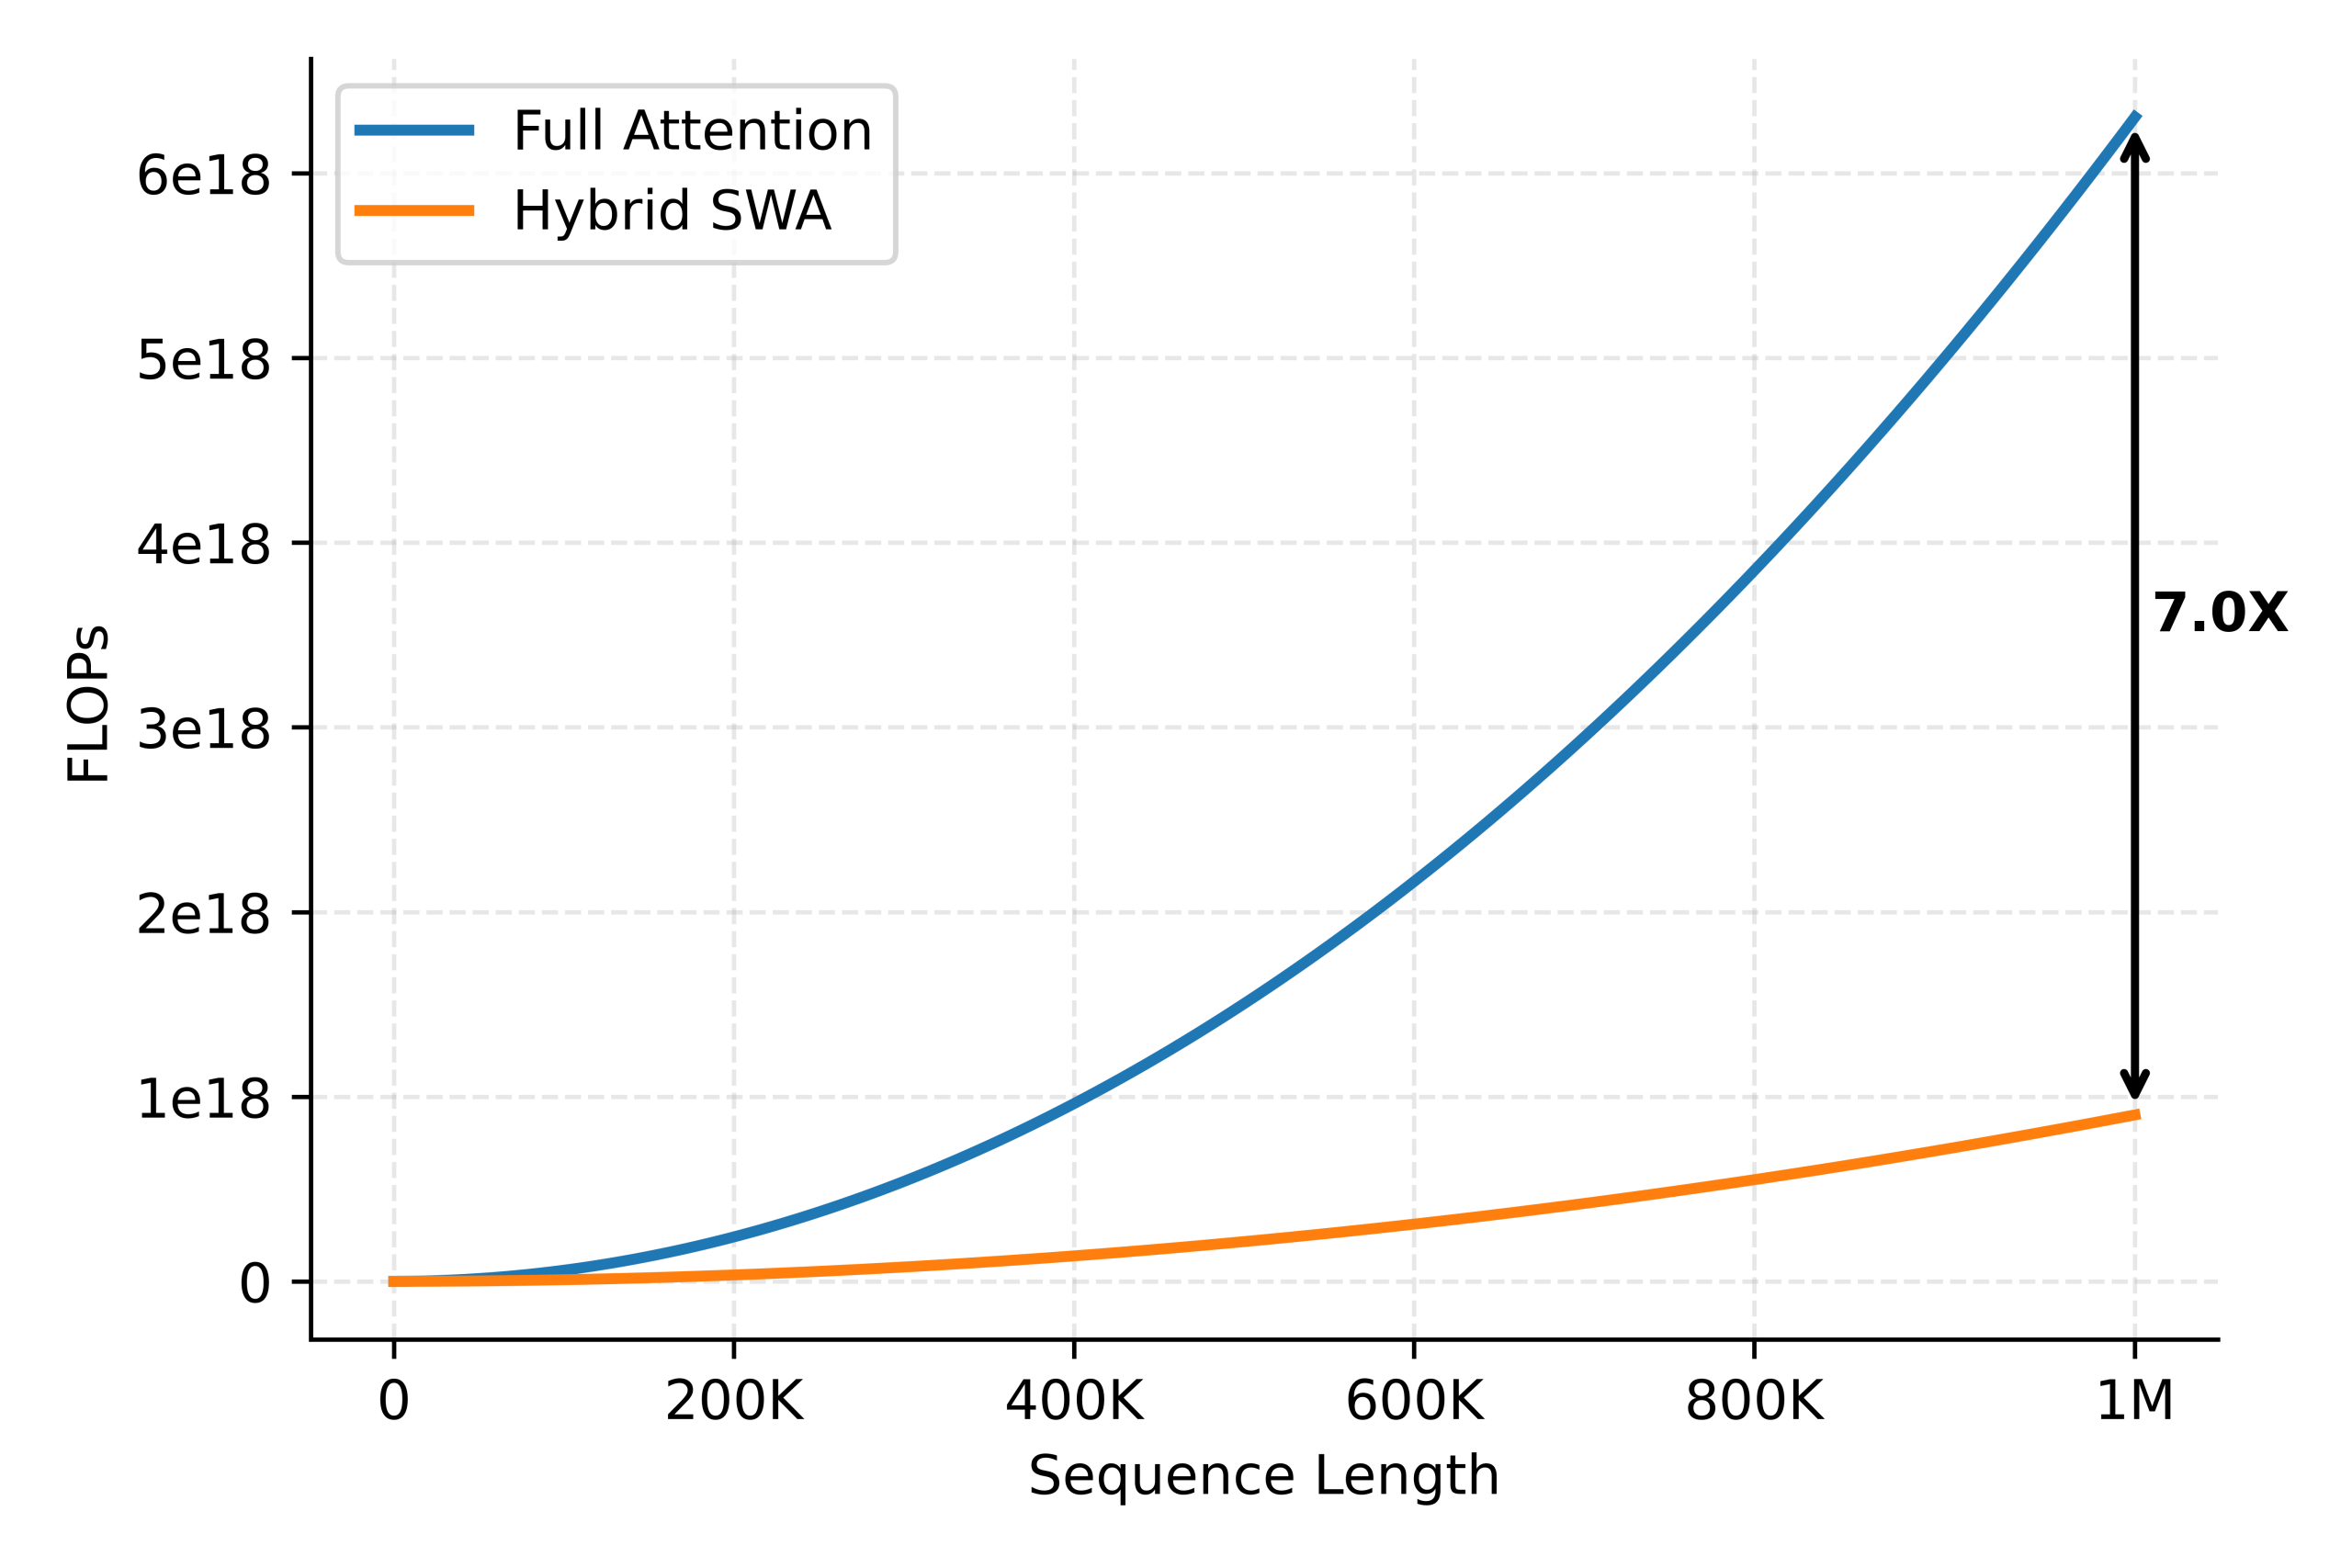
If you serve AI models as a part of your product stack, you’ve likely wondered what kind of scale your GPU cluster tops out at. With some rudimentary knowledge about your hardware and model architecture, we can work out the … Read more

LLM Inference Handbook

bentoml.com
llm-inference-handbook

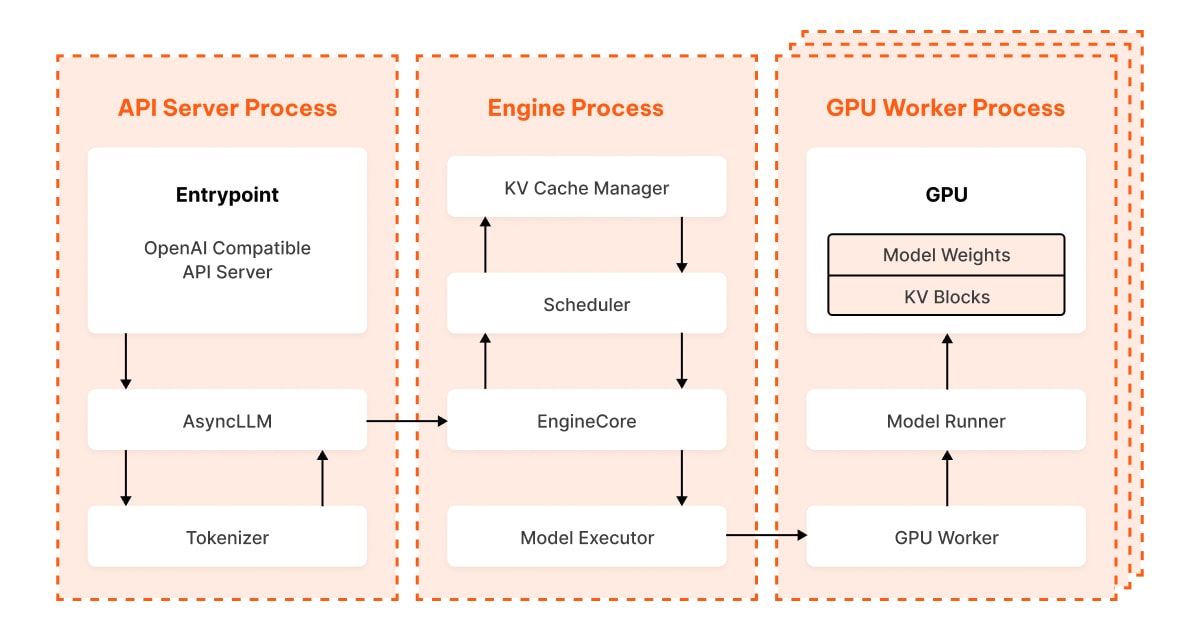
LLM Inference in Production is your technical glossary, guidebook, and reference – all in one. It covers everything you need to know about LLM inference, from core concepts and performance metrics (e.g., Time to First Token and Tokens per Second), … Read more

Fast LLM Inference From Scratch (using CUDA)

andrewkchan.dev
fast-llm-inference-from-scratch-(using-cuda)

Contents Pushing single-GPU inference throughput to the edge without libraries Source code for this article on GitHub. This post is about building an LLM inference engine using C++ and CUDA from scratch without libraries. Why? In doing so, we can … Read more

AMD Inference

github.com
amd-inference

{{ message }} This commit does not belong to any branch on this repository, and may belong to a fork outside of the repository. You can’t perform that action at this time.

Fast GPT-2 inference written in Fortran

github.com
fast-gpt-2-inference-written-in-fortran

{{ message }} This commit does not belong to any branch on this repository, and may belong to a fork outside of the repository. You can’t perform that action at this time. You signed in with another tab or window. … Read more

Type Inference That Sticks

jaredforsyth.com
type-inference-that-sticks

What if type inference felt like a real-time conversation, instead of emailing code back and forth? With type inference, compilers are faced with a difficult task: intuiting what types a user had in mind (but didn’t write down) while writing … Read more