Semgrep: GLM 5.2 beats Claude in our Cyber Benchmarks
semgrep.dev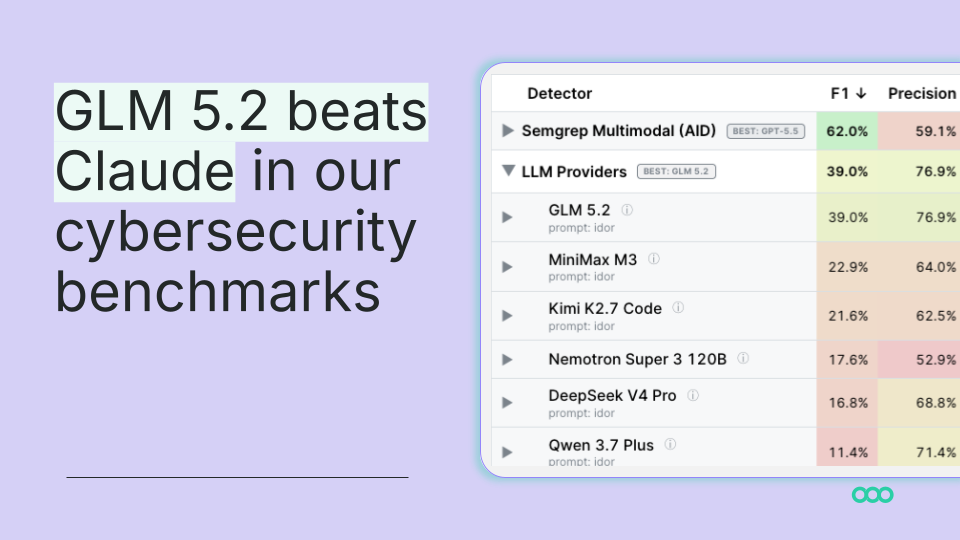
We ran a set of popular open-source models against our IDOR benchmark, the same dataset and the same prompt we’ve used to evaluate frontier coding agents. The result surprised us: GLM 5.2, an open-weight model from Zhipu AI, scored a … Read more