How we made a text-to-speech model respond in sub-50 ms
nari-labs.com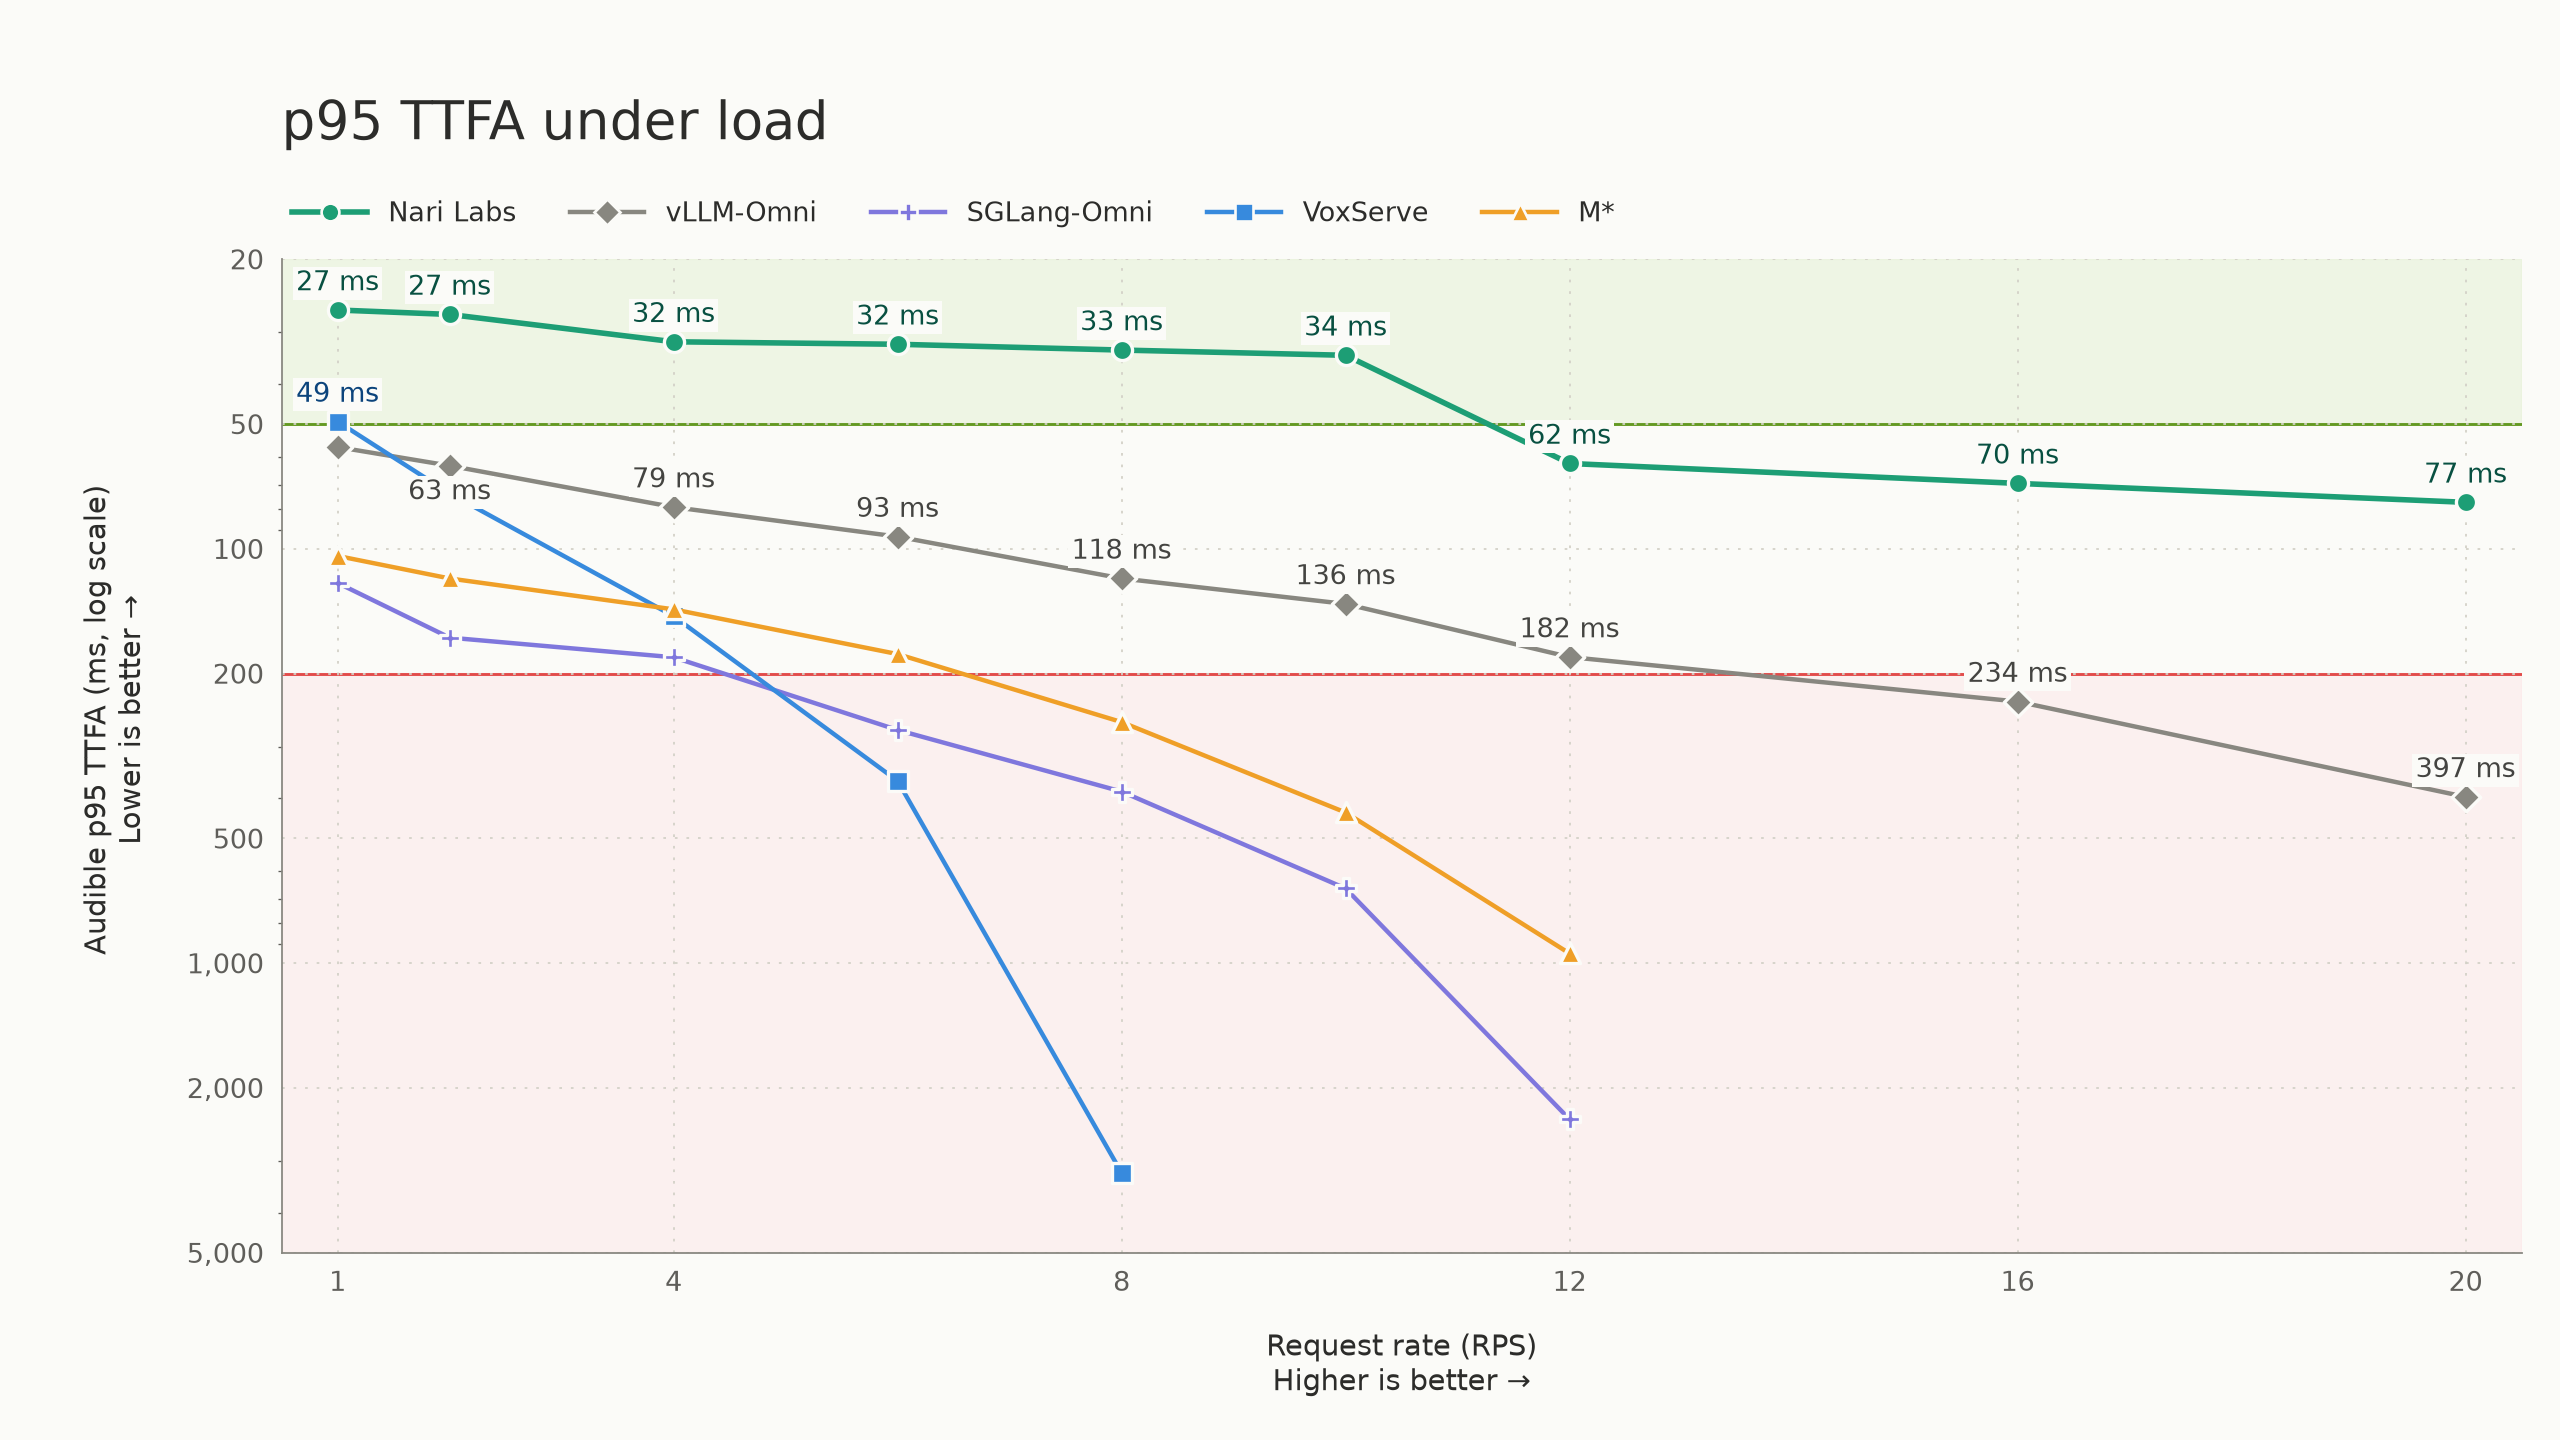
TL;DR Our Qwen3-TTS 1.7B CustomVoice implementation achieves 10 requests per second (RPS) and sub-50 ms p95 time-to-first-audio (TTFA) while maintaining real-time playback on a single NVIDIA H100 SXM. × We compare five implementations: ours, vLLM-Omni, SGLang-Omni, VoxServe, and M*, under … Read more